Guidance is becoming a cheat code for LLMs (with Loooop)
Guidance can dramatically improve prompt following and sample quality in image and video generation, simply by changing how a trained model is sampled.1 Classifier-free guidance (CFG) is a standard ingredient in Stable Diffusion 32 and Wan3. Its benefits are valuable enough that FLUX.1 [dev] is trained to distill guidance directly into the model.4
Can language models benefit in the same way? There is a catch: applying guidance to each next-token prediction does not generally produce the desired guided joint distribution over the full token sequence. The two procedures normalize probabilities differently. Looped models offer a way to narrow this gap: when predictions from different loops are close, the normalization error is second order in their logit difference, while guidance changes token preferences at first order. We will derive this connection, then measure how close those predictions are in practice.
01Why diffusion guidance needs no normalizer
Start with a conditional density \(p(x\mid c)\), where \(c\) might be a text prompt. Suppose we want to favor samples that are especially characteristic of that condition. One way to express this preference is to tilt the density:
The ratio \(p(x\mid c)/p(x)\) rewards samples that the condition helps explain. At \(w=0\), we recover ordinary conditional generation. Increasing \(w\) strengthens that preference. The denominator \(Z_w(c)\) makes the density integrate to one.
Diffusion uses the corresponding construction at each noise level \(t\). With \(x_t\) denoting the whole noisy sample, take the log-gradient of the tilted density:
This is the score combination behind classifier-free guidance1. The normalizer depends on the condition and noise level, but not on the sample coordinates \(x_t\), so its gradient is zero. We do not approximate or discard the normalizer: differentiation removes it exactly. This lets us compute the guided score without evaluating the integral defining \(Z_{t,w}\).
Show the derivation and its scope
At a fixed noise level, assume differentiable positive densities and a finite normalizer. Taking logarithms of the noisy version of Equation (1) gives
Differentiate with respect to \(x_t\). Since \(Z_{t,w}(c)\) is constant in that variable, the last term disappears, giving Equation (2). Bayes' rule also gives
Thus the same tilt can be written as \(p_t(x_t\mid c)\,p_t(c\mid x_t)^w\), up to a factor depending only on \(c\). With exact scores, this is an exact identity at that noise level.
Scope of the identity. The normalizer cancels at each fixed noise level. This identity alone does not guarantee that the full sampling process produces the target distribution in Equation (1). Reweighting a distribution and then adding noise generally differs from adding noise first and then reweighting. Sander noted this limitation in his correction5; Bradley and Nakkiran6 and Chidambaram et al.7 give formal counterexamples. We use the score identity at a fixed noise level here.
02Token-level guidance and the joint distribution
Guidance already exists in autoregressive LLMs. Stay on topic with Classifier-Free Guidance8 applies CFG by contrasting next-token predictions with and without the conditioning prompt, while keeping the generated prefix. Contrastive decoding9 uses a weaker model as the reference; DoLa10 uses predictions from earlier layers. Here we study their shared core idea: combine two next-token predictions, then normalize.
The joint distribution assigns a probability to every complete token sequence. Applying guidance to that distribution means reweighting each sequence and normalizing once. Token-level guidance instead normalizes separately at each prefix. These operations generally produce different sequence probabilities.
As Sander noted in his 2022 blog post:
“my hunch is that diffusion guidance works so well precisely because we are able to apply it to the joint distribution”
Let \(p_K(v\mid s)\) be the next-token prediction we want to strengthen and \(p_E(v\mid s)\) the reference prediction, for candidate token \(v\) after generated prefix \(s\). For CFG, these use different prompt conditioning; later, they will come from different loops of the same model. Suppress the fixed conditioning in the notation, assume positive token probabilities, and define the unnormalized token weight \(a\) and its local normalizer \(C\):
The guided next-token distribution is \(q(v\mid s)=a(v\mid s)/C(s)\). If \(z_K\) and \(z_E\) are the two predictors' logits (their unnormalized token scores), this is exactly what softmax of \((1+w)z_K-wz_E\) computes. For a full sequence \(y=(y_1,\ldots,y_T)\) of fixed length \(T\), multiplying the unnormalized token weights gives
Here \(P_K(y)\) and \(P_E(y)\) are the sequence probabilities obtained by multiplying each predictor's token probabilities. The guided joint distribution \(Q_{\rm joint}\) normalizes \(A(y)\) once. The distribution \(Q_{\rm local}\) produced by token-level guidance accumulates a normalizer at every prefix:
Both rules assign the same unnormalized weight to a sequence. But \(Z\) is shared by every sequence, whereas \(\prod_t C(y_{<t})\) depends on the prefixes along that particular sequence. This sequence-dependent denominator is the normalization mismatch.
How would the guided joint distribution choose each token?
Every joint distribution admits a sequential factorization. The issue is whether the simple local rule gives us the right conditionals. Let \(H(s)\) be the total unnormalized guided weight of every possible completion after prefix \(s\). The exact conditional of the joint target is
The term \(H(sv)\) accounts for all the futures opened up by choosing \(v\). Ordinary local guidance omits it. Computing it exactly is usually impractical, because it requires summing over possible continuations.
Let \(A_{\rm past}(s)\) be the product of guided weights along the prefix. Define \(H(s)\) as the sum of the remaining products over completions of total length \(T\), with \(H(y)=1\) for a complete sequence. It satisfies
The joint target's marginal prefix mass is \(Q_{\rm joint}(s)=A_{\rm past}(s)H(s)/Z\). Divide the mass of \(sv\) by the mass of \(s\):
This gives Equation (4). The local rule agrees whenever \(H(sv)\) is the same for every candidate \(v\) at that prefix.
Additionally, computing the full-sequence normalizer \(Z\) exactly is impractical for real LLMs: it requires summing over all possible future token sequences, whose number grows exponentially with length.
If the guided joint distribution is our target, practical token-level guidance therefore tolerates a normalization error. Exact token choices require the future-completion sums in Equation (4); the local rule avoids them by normalizing only the next-token scores. The question is how to make the resulting error small.
A tiny example makes the difference visible
Suppose a sequence has just two tokens. Both predictors choose \(A\) or \(B\) with probability \(1/2\). After \(A\), both remain uniform over \(1,2\). After \(B\), the reference is still uniform but the stronger predictor assigns probabilities \(0.9,0.1\). Token-level guidance cannot change the first decision: the predictors agree there. The guided joint distribution can, because it accounts for the guided weight of the continuations after \(B\).
Same token weights, different sequence probabilities
If the two guidance rules were equivalent, they would give the same probability of starting with B. Shrink the predictor difference to see the gap close.
Probability of starting with B
12.1 percentage-point gap. Even the first-token probabilities differ.
Show the probabilities and normalizers
Both predictors start with a 50–50 choice of A or B. After B, the stronger predictor uses (0.90, 0.10); the reference uses (0.50, 0.50).
The normalizers measure the total guided weight of the next-token options. Token-level guidance divides by each prefix's normalizer separately. The guided joint distribution retains their relative weights when comparing full sequences, so a larger normalizer after B makes B more likely from the start.
Here, the joint probability of starting with B is \(C(B)/(1+C(B))\).
| Sequence | Strong | Reference | Token-level | Joint target |
|---|---|---|---|---|
| A1 | 0.250 | 0.250 | 0.250 | 0.189 |
| A2 | 0.250 | 0.250 | 0.250 | 0.189 |
| B1 | 0.450 | 0.250 | 0.494 | 0.614 |
| B2 | 0.050 | 0.250 | 0.006 | 0.008 |
Sequence total variation: . This measures the difference across all four sequences: half the sum of their absolute probability differences. It is zero when the distributions agree.
03Loooop
A looped Transformer applies the same block of layers repeatedly before predicting the next token. Huginn11 and Ouro12 implement this idea in different ways. Each completed loop gives a hidden state that can be converted into next-token logits: \(z_E\) after an earlier loop \(E\), and \(z_K\) after the final loop \(K\).
The earlier prediction serves as the weaker reference for guiding the final prediction. Both come from the same model on the same text prefix; the difference is how many loops of computation they use.
LoopCD13 uses these predictions for guidance without additional training. Its logit variant strengthens the final logits \(z_K\) along the difference \(z_K-z_E\). Applying softmax gives \(q\), the guided next-token probability distribution:
LoopCD's logit variant uses the first loop as its reference. The paper also combines hidden states before converting them into logits; the analysis below concerns the logit rule in Equation (5).
| Model / task | Guidance | Before | After |
|---|---|---|---|
| Ouro-2.6B-ThinkingAIME 2024 · pass@1 | LogitsLoop 1 guides loop 4 Adaptive strength | 61.88 | 73.33 |
| Huginn · 32 loopsHumanEval · pass@1 | Hidden statesLoop 7 guides loop 32 | 22.56 | 31.71 |
Before and after use the same number of loops: 4 for Ouro and 32 for Huginn. Guidance combines an earlier prediction or state with the final one; it does not add loops. Settings: Tables 1, 3, and A4.
Because every loop repeats the same computation, its predictions are expected to stay close as the hidden state is refined. This gives us a route back to the normalization problem: close loop predictions can make token-level guidance a better approximation to the guided joint distribution. Below we show how the error depends on their logit difference, then measure that difference.
Why loops help
The key assumption is that predictions from different loops have similar logits. Under this small-difference assumption, we can bound the local normalizer \(C(s)\).
At a fixed prefix, write \(\delta=z_K-z_E\). After removing an irrelevant constant offset, assume \(\delta=\epsilon d\), with \(d\) bounded and \(\epsilon\) small. Keep the guidance strength fixed and bounded. A Taylor expansion gives
The constant and first-order terms cancel. Guidance changes token log-odds at first order; its local log-normalization cost starts at second order.
This is why similar loop outputs help: guidance changes token preferences at first order in \(\epsilon\), while the local log-normalizer grows only at second order.
Derive Equation (6): the exact identity and Taylor expansion
First, the local normalizer satisfies the exact identity
Proof of Equation (7). Suppress the prefix and use \(\log q=(1+w)\log p_K-w\log p_E-\log C\). Rearranging gives
Taking the expectation over \(v\sim p_K\) yields Equation (7). For \(w\geq0\), both KL terms are nonnegative, so \(\log C(s)\geq0\). This identity does not require small logit differences.
To find how quickly \(\log C(s)\) approaches zero when the predictions are close, define the log moment-generating function of the logit difference under the reference distribution:
Softmax gives \(p_K(v)=p_E(v)e^{\delta(v)-\psi(1)}\). Substituting into the definition of \(C\), we obtain the exact expression
For \(\delta=\epsilon d\) with uniformly bounded \(d\), and bounded \(\alpha\), expand
The two linear terms are both \((1+w)\mu\). Their difference is zero; the remaining quadratic coefficient is
Adding any constant to \(\delta\) adds a linear term to \(\psi\), which cancels in exactly the same way. The relevant assumption concerns variation across tokens, not the arbitrary origin of the logits.
For comparison, the change in log-odds relative to the final predictor is exactly
For fixed \(w\), this is \(O(\epsilon)\), whereas \(\log C\) begins at \(O(\epsilon^2)\).
Bounding the error over the full sequence
Suppose \(0\leq\log C(s)\leq\eta\) at every prefix of a length-\(T\) sequence. Equation (3) then bounds the log-probability difference between token-level guidance and the guided joint distribution:
Equation (8) bounds the full-sequence error by \(T\eta\). Under the uniform small-difference assumption, \(\eta=O(\epsilon^2)\), so this error is \(O(T\epsilon^2)\): close predictions let the token-level rule approximate the guided joint distribution without summing over future sequences.
Prove the sequence bound, including the global normalizer
Set \(D(y)=\prod_t C(y_{<t})\). Since \(A(y)=Q_{\rm local}(y)D(y)\), summing over sequences gives
The prefix bound gives \(1\leq D(y)\leq e^{T\eta}\) for every sequence. Its expectation obeys the same bounds, so \(0\leq\log Z\leq T\eta\). Finally,
Both terms lie in \([0,T\eta]\), establishing Equation (8). This argument retains the global normalizer rather than dropping it.
A finite, non-asymptotic bound is also available. Let \(R=\max_v\delta(v)-\min_v\delta(v)\). In the preceding proof, \(\psi''(\alpha)\) is the variance of \(\delta\) under an exponentially tilted distribution, and is at most \(R^2/4\). The remainder for linear interpolation of \(\psi\) at 0 and 1, evaluated at \(1+w\), gives
Thus a uniform range bound \(R(s)\leq R_*\) yields \(\eta=w(1+w)R_*^2/8\). This makes clear why average RMS alone cannot certify the sequence guarantee. The proof uses a fixed finite horizon and common positive support; unrestricted generation with EOS needs corresponding control of length and the partition function.
04Are predictions from different loops actually closer?
We compared two looped models, Huginn-0125 and Ouro-2.6B, with two ordinary Transformers, Qwen2.5-3B and Pythia-2.8B. Each model saw the same 1,024 text prefixes: eight positions on each of 128 GSM8K development questions. At each prefix, we compared the model's next-token logits partway through its computation with its own final logits.
Here, depth \(k\) means the number of completed loops in a looped model, or completed layers in an ordinary Transformer. The final depth \(K\) stays fixed. Let \(V\) be the vocabulary size and \(v\in\{1,\ldots,V\}\) a candidate token's index. Then \(z_{k,v}(s)\) is that token's score after depth \(k\), on the same text prefix \(s\).
For each \(k\), compute the change to the final score, \(\delta^{(k)}_v(s)=z_{K,v}(s)-z_{k,v}(s)\). Remove its vocabulary mean, \(\bar\delta^{(k)}(s)=V^{-1}\sum_v\delta^{(k)}_v(s)\), because adding the same constant to every logit does not change softmax. We measure the remaining change with
Intuitively, this measures how much the next-token scores change between an intermediate depth and the final depth. It is the standard deviation of those score changes across the vocabulary. A smaller value means the predictions vary less as the model performs more loops or layers.
In the plot, we vary \(k\), keep the prefix and final depth \(K\) fixed, and average the RMS over the 1,024 prefixes. The horizontal position is \(k/K\): 50% means halfway through that model. The depths used for the quarter, half, and three-quarter comparisons are:
| Model | Intermediate \(k\): 25%, 50%, 75% | Fixed final \(K\) |
|---|---|---|
| Huginn-0125 | Loops 8, 16, 24 | 32 loops |
| Ouro-2.6B | Loops 1, 2, 3 | 4 loops |
| Qwen2.5-3B | Layers 9, 18, 27 | 36 layers |
| Pythia-2.8B | Layers 8, 16, 24 | 32 layers |
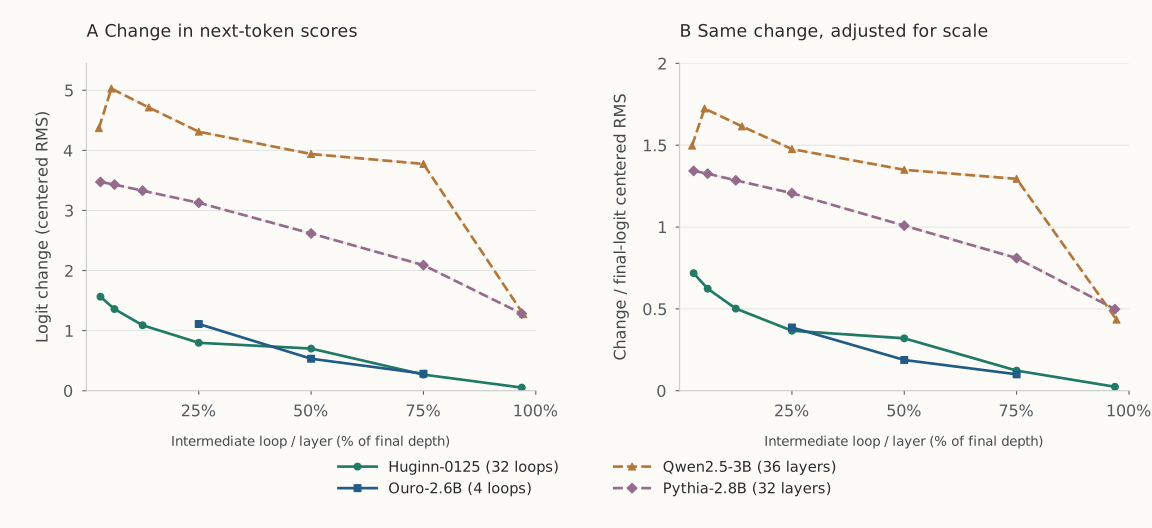
The looped models' mean gaps are 2.8–14.1 times smaller across all twelve comparisons. Every paired 95% bootstrap interval for the ratio lies below one. The ordering also holds after scale normalization and when using only question prefixes, before any answer text.
Measurement details
The models are frozen base checkpoints. Inputs use a common plain-text, eight-shot Q/A format. Answer-prefix positions come from cached Huginn-32 continuations, with no filtering for answer correctness. We selected shared character boundaries that round-trip exactly through all four tokenizers, including the prompt boundary. This matches text, not token IDs across different vocabularies.
Intermediate hidden states are converted into logits using each architecture's existing output computation, including Huginn's final coda layers, normalization, and vocabulary head. We did not fit an additional prediction head. Native forwards use BF16; full-vocabulary statistics use float64 at temperature one. A native-forward check and a future-token control passed at all 84 audited model/depth settings. An independent audit recomputed 28,672 depth-position records.
Intervals resample the 128 questions, retaining each question's eight positions together; paired comparisons resample the same questions for both models. We used 5,000 bootstrap draws. These are individual intervals over the sampled questions, not simultaneous intervals or estimates of variation across training seeds.
The twelve comparisons pair each looped model with each ordinary Transformer at \(k/K=25\%,50\%,75\%\). At half depth, Huginn's gap is 0.268 times Pythia's, with a 95% interval of [0.261, 0.276]; Ouro's is 0.203 times Pythia's, with interval [0.199, 0.209].
The normalized gap divides by the final logits' centered RMS at each position before averaging. Centered RMS weights vocabulary entries uniformly; the variance in Equation (6) weights them by the reference probabilities \(p_E\). The plot is a direct diagnostic of logit similarity. Its vertical axes start at zero, and lines connect measured depths. At \(k=K\), the gap is zero by definition, so that endpoint is omitted.
Depth fractions match relative progress through each model, rather than FLOPs. The checkpoints differ in architecture, training, vocabulary, and size; this comparison measures their predictions using their existing output computations.
LoopCD's first-loop reference deserves separate care: it is 1/32 of the deployed depth for Huginn but 1/4 for Ouro. We therefore do not present “first versus final” as a matched-depth comparison. The source report includes that diagnostic separately.
How accurate is the quadratic approximation itself?
We also computed the exact \(\log C\) and its quadratic approximation. At a quarter depth with \(w=0.5\), the median relative error across the 1,024 positions is 76.9% for Huginn and 75.3% for Ouro, versus 29.2% for Qwen and 27.6% for Pythia. Here relative error means \(|\text{quadratic}-\log C|/\max(\log C,10^{-12})\); the floor is inactive at these positions. The looped models have smaller absolute normalizers in this comparison, but not smaller relative Taylor error.
Even at three-quarter depth, the largest observed absolute centered logit difference is 5.60 for Huginn and 6.44 for Ouro. A small vocabulary-average gap can coexist with larger differences on particular tokens. Equation (8) uses a uniform bound over prefixes, whereas the plot summarizes average logit differences.
The smaller logit gaps support the proposed mechanism: loop predictions stay closer, making smaller normalization errors plausible. Under the small-difference assumption, guidance changes token preferences at first order while the normalization error grows only at second order. This gives looped models a natural route toward effective token-level guidance that stays close to the desired joint distribution.
05Loops and diffusion, beyond guidance
Guidance connects looped models and diffusion through a shared idea: use a weaker prediction to steer a stronger one. In diffusion, autoguidance uses a smaller, less-trained model as the reference.14 A looped model can obtain its reference from an earlier loop. But the connections now extend beyond guidance to how these models are trained and how they spend computation at inference.
LoopFormer makes this connection explicit by giving each loop an internal time \(t\) and step size \(\Delta t\).15 Its shortcut-consistency objective aligns computations of different lengths, borrowing timestep conditioning and shortcut training from diffusion. The same model can then take fewer, larger steps or more, smaller steps according to its computation budget.
Thinking with Looped Flows connects recurrent computation directly to denoising.16 It trains a recurrent denoiser on progressively less noisy versions of a solution. At inference, a probability flow transforms noise into a solution while carrying the recurrent state between steps; a finer time grid allocates more computation.
The bigger picture is test-time scaling through iterative refinement. Both looped models and diffusion break a difficult generative task into smaller, easier updates and let us vary how many updates we perform at inference. Guidance is one consequence of that structure. Their shared use of repeated computation suggests that the connection between loops and diffusion may run deeper than it first appears.
References
- Jonathan Ho and Tim Salimans. Classifier-Free Diffusion Guidance. arXiv, 2022. ↩1 ↩2
- Patrick Esser et al. Scaling Rectified Flow Transformers for High-Resolution Image Synthesis. ICML, 2024. ↩
- Wan Team. Wan: Open and Advanced Large-Scale Video Generative Models. arXiv, 2025. ↩
- Black Forest Labs. FLUX.1 [dev]. Model card, 2024. ↩
- Sander Dieleman. Guidance: a cheat code for diffusion models. May 26, 2022; including the May 29 correction. ↩1 ↩2
- Arwen Bradley and Preetum Nakkiran. Classifier-Free Guidance is a Predictor-Corrector. arXiv, 2024. ↩
- Muthu Chidambaram et al. What does guidance do? A fine-grained analysis in a simple setting. arXiv, 2024. ↩
- Guillaume V. Sanchez et al. Stay on topic with Classifier-Free Guidance. arXiv, 2023. ↩
- Xiang Lisa Li et al. Contrastive Decoding: Open-ended Text Generation as Optimization. arXiv, 2022. ↩
- Yung-Sung Chuang et al. DoLa: Decoding by Contrasting Layers Improves Factuality in Large Language Models. arXiv, 2023. ↩
- Jonas Geiping et al. Scaling up Test-Time Compute with Latent Reasoning: A Recurrent Depth Approach. arXiv, 2025. ↩
- Rui-Jie Zhu et al. Scaling Latent Reasoning via Looped Language Models. arXiv, 2025. ↩
- Weihao Liu et al. Decoding Looped Transformers Better for (Almost) Free. arXiv, 2026. ↩1 ↩2
- Tero Karras et al. Guiding a Diffusion Model with a Bad Version of Itself. NeurIPS, 2024. ↩
- Ahmadreza Jeddi, Marco Ciccone, and Babak Taati. LoopFormer: Elastic-Depth Looped Transformers for Latent Reasoning via Shortcut Modulation. arXiv, 2026. ↩
- Ayhan Suleymanzade, Chanhyuk Lee, Floor Eijkelboom, Nicholas M. Boffi, İsmail İlkan Ceylan, and Jinwoo Kim. Thinking with Looped Flows. arXiv, 2026. ↩